Zero Downtime Deployments with Terraform
Use Terraform lifecycle rules, blue/green, rolling and canary strategies with health checks to update infrastructure without service interruptions.
Read moreBlog posts in the Performance category
Use Terraform lifecycle rules, blue/green, rolling and canary strategies with health checks to update infrastructure without service interruptions.
Read more
Unified observability across on‑prem and public clouds with OpenTelemetry, RUM, synthetic tests and AI for proactive issue detection.
Read more
Compare AWS and Azure for multiplayer game hosting: performance, costs, GPUs, latency, scalability and UK region differences.
Read more
Narrow SLA definitions and capped credits can leave your business exposed—use this checklist to verify uptime, support and enforcement.
Read more
Unified logs, metrics and traces to cut hosting costs, reach 99.9% uptime and reduce MTTR from 45 to 8 minutes.
Read more
Low-cost distributed tracing for Kubernetes using object storage and a no‑index architecture; integrates with Prometheus and Loki.
Read more
Compare Consul and Istio on platform support, traffic control, observability, resource use and when to choose each.
Read more
GPU hourly rates in 2025 varied up to 10× by region and provider; spot pricing, egress and co-location drive 2–5× savings.
Read more
Build vendor reporting frameworks with KPIs, automation and AI to cut cloud costs, boost delivery and reduce incidents.
Read more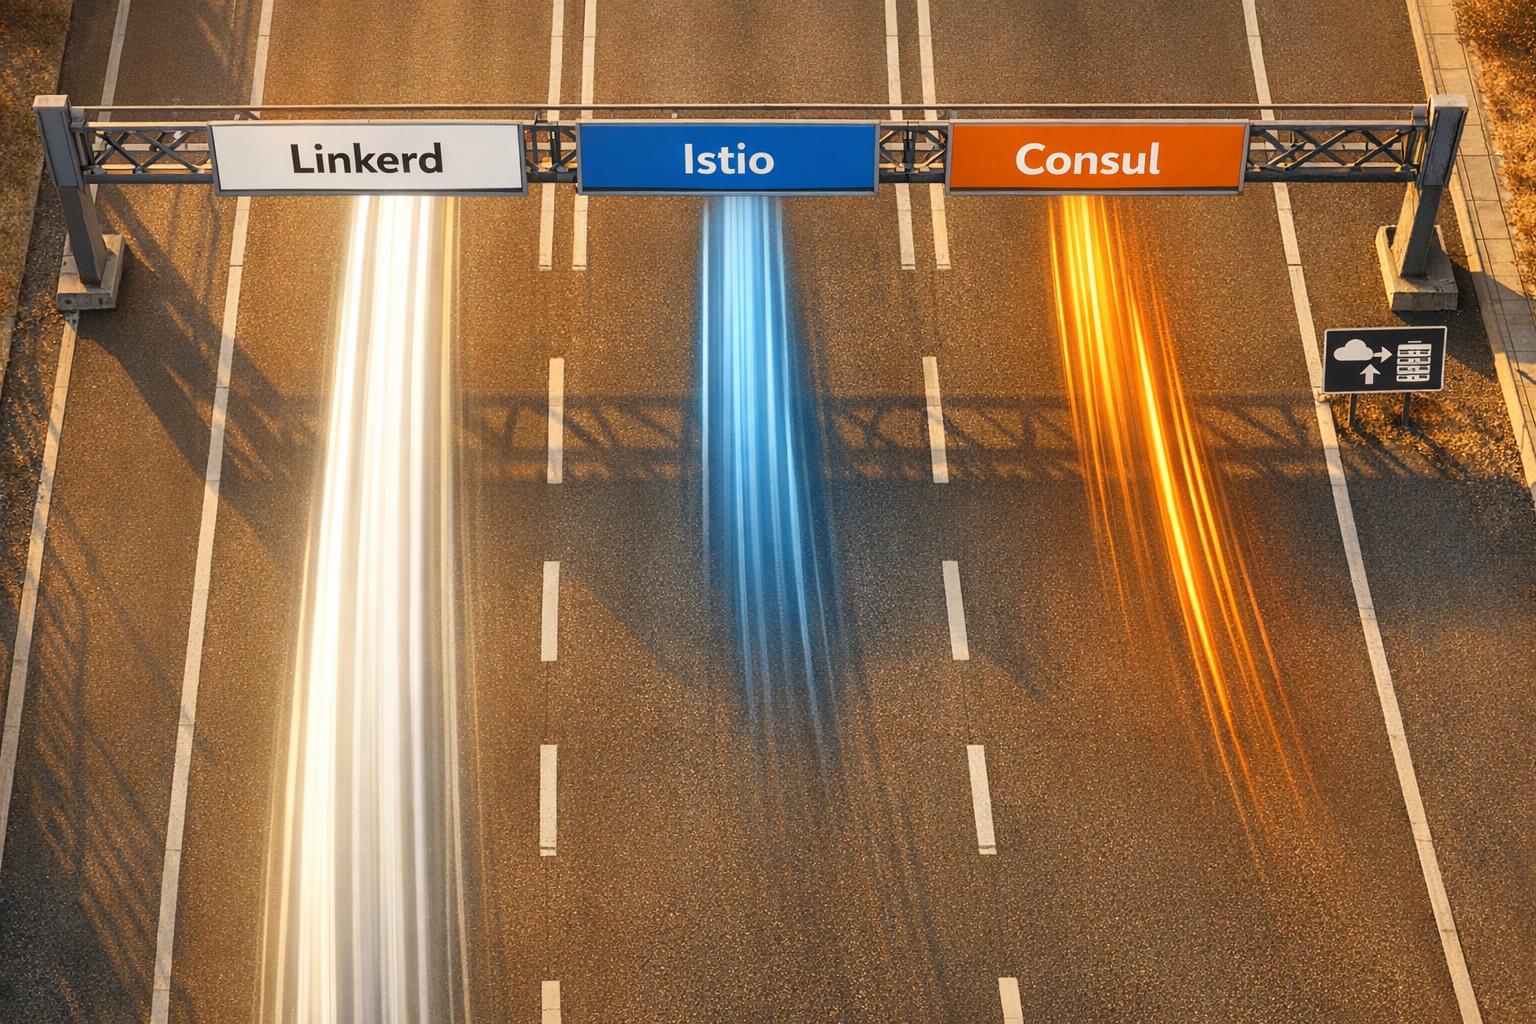
Latency and resource comparison of Istio, Linkerd and Consul — Linkerd leads in speed, Istio in features, Consul suits HashiCorp/hybrid setups.
Read more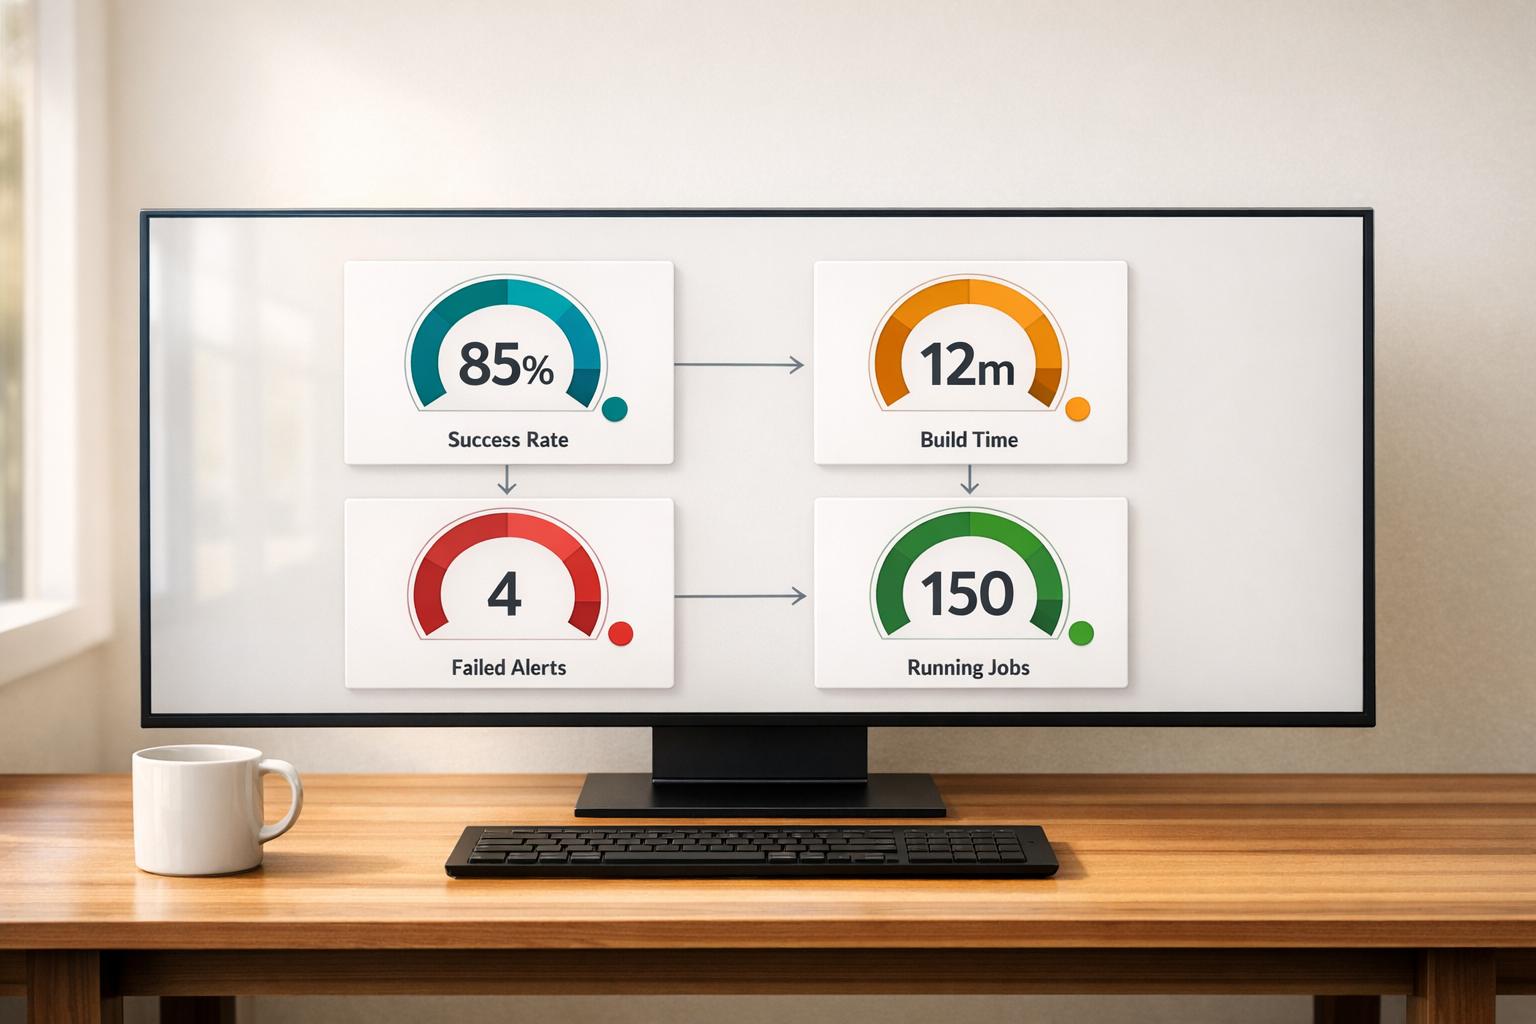
Alert on four core CI/CD metrics to catch pipeline issues early and keep delivery fast and reliable.
Read more
Zero-downtime Kubernetes guide: rolling updates, readiness probes, blue‑green/canary releases, preStop hooks and Argo CD automation.
Read more