Supervisor-Led Agent Teams: Cost and Latency Trade-Offs
Measure £/successful answer and P50/P95 usable-answer time to decide when supervisor-led agent teams justify extra cost and delay.
Read moreBlog posts in the Performance category
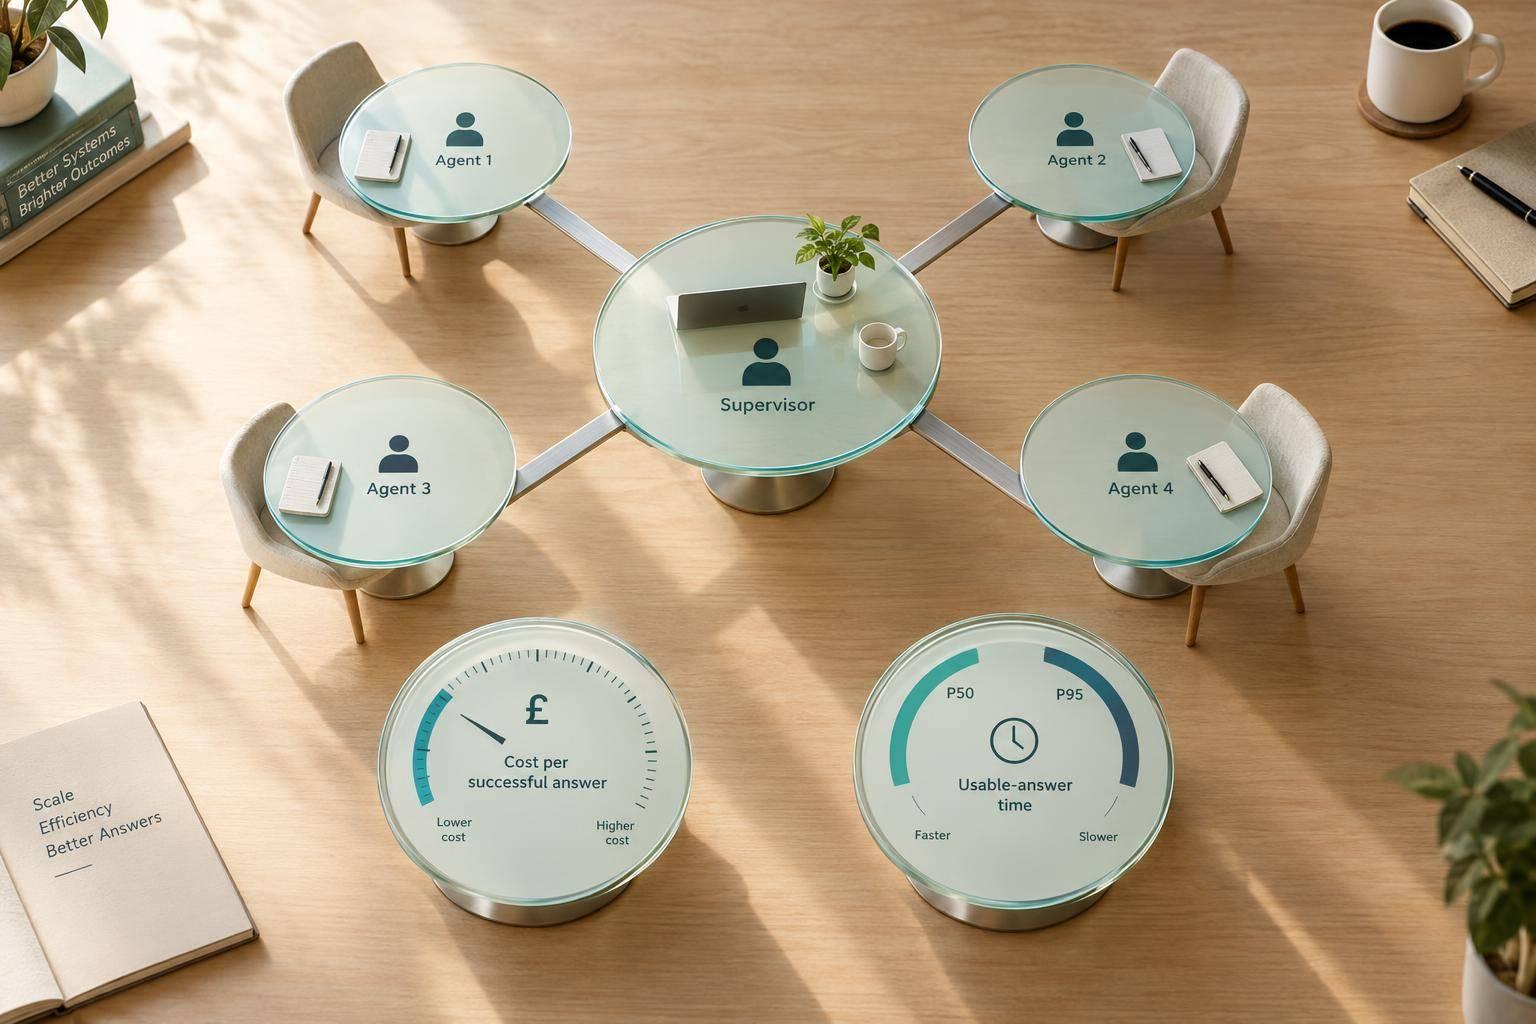
Measure £/successful answer and P50/P95 usable-answer time to decide when supervisor-led agent teams justify extra cost and delay.
Read more
Treat Retry-After as a minimum and avoid retry storms: use capped exponential backoff with jitter, idempotency and bounded queues.
Read more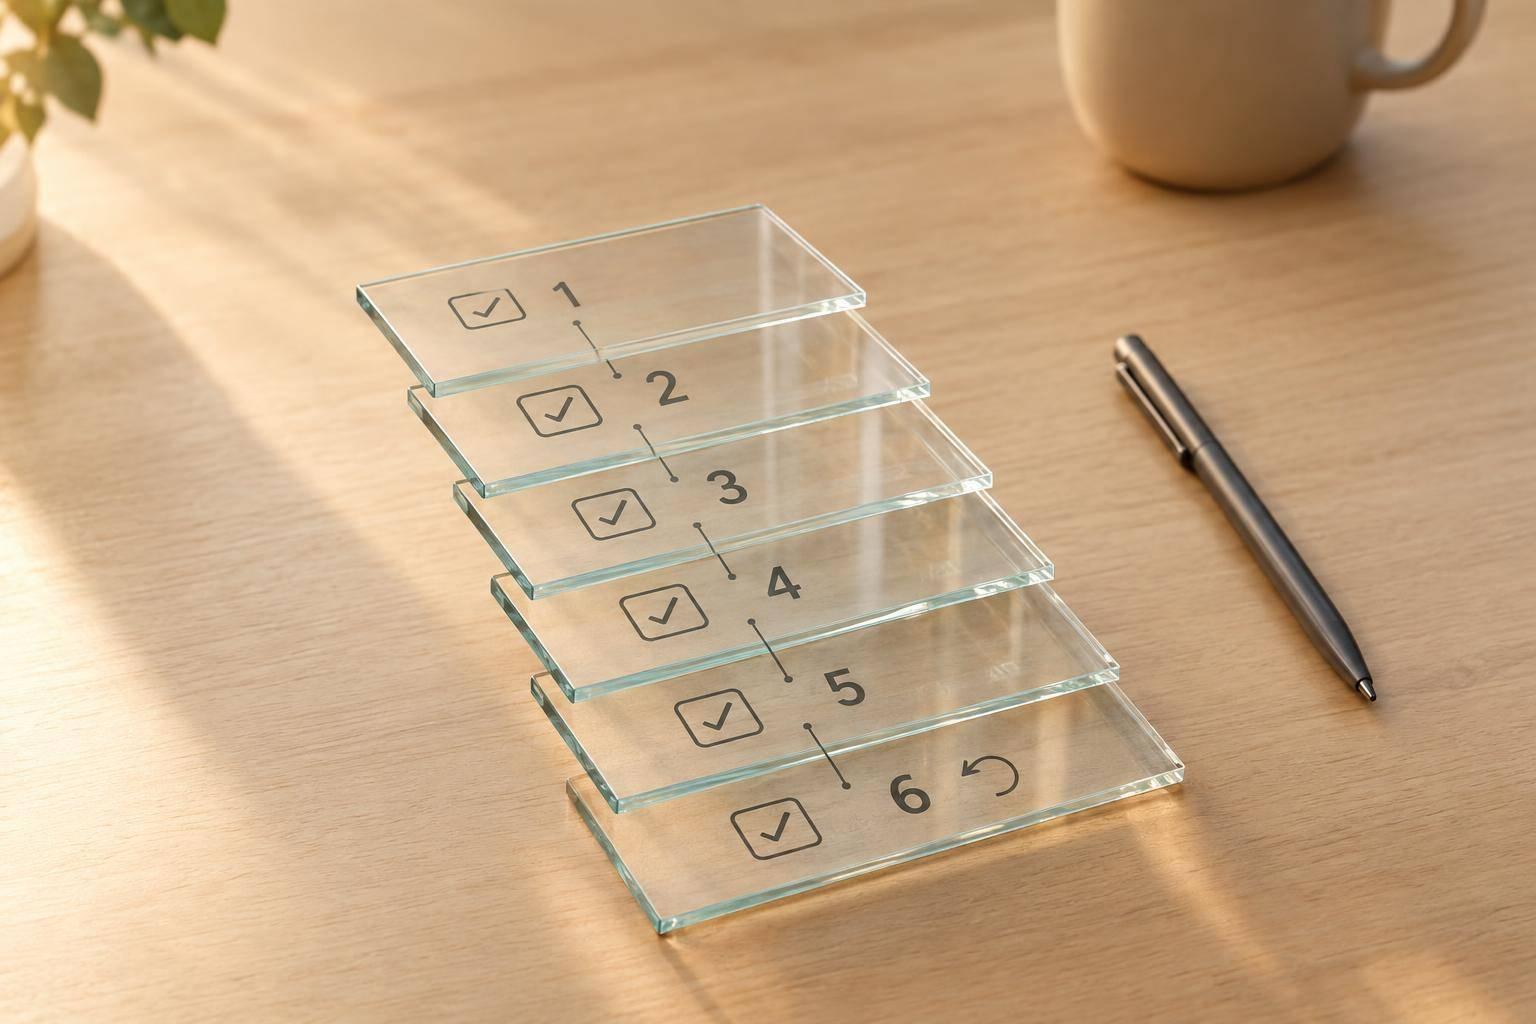
Six-step checklist for LLM SDK upgrades: map breaking changes to apps and owners, validate requests/responses; rehearse rollout and rollback.
Read more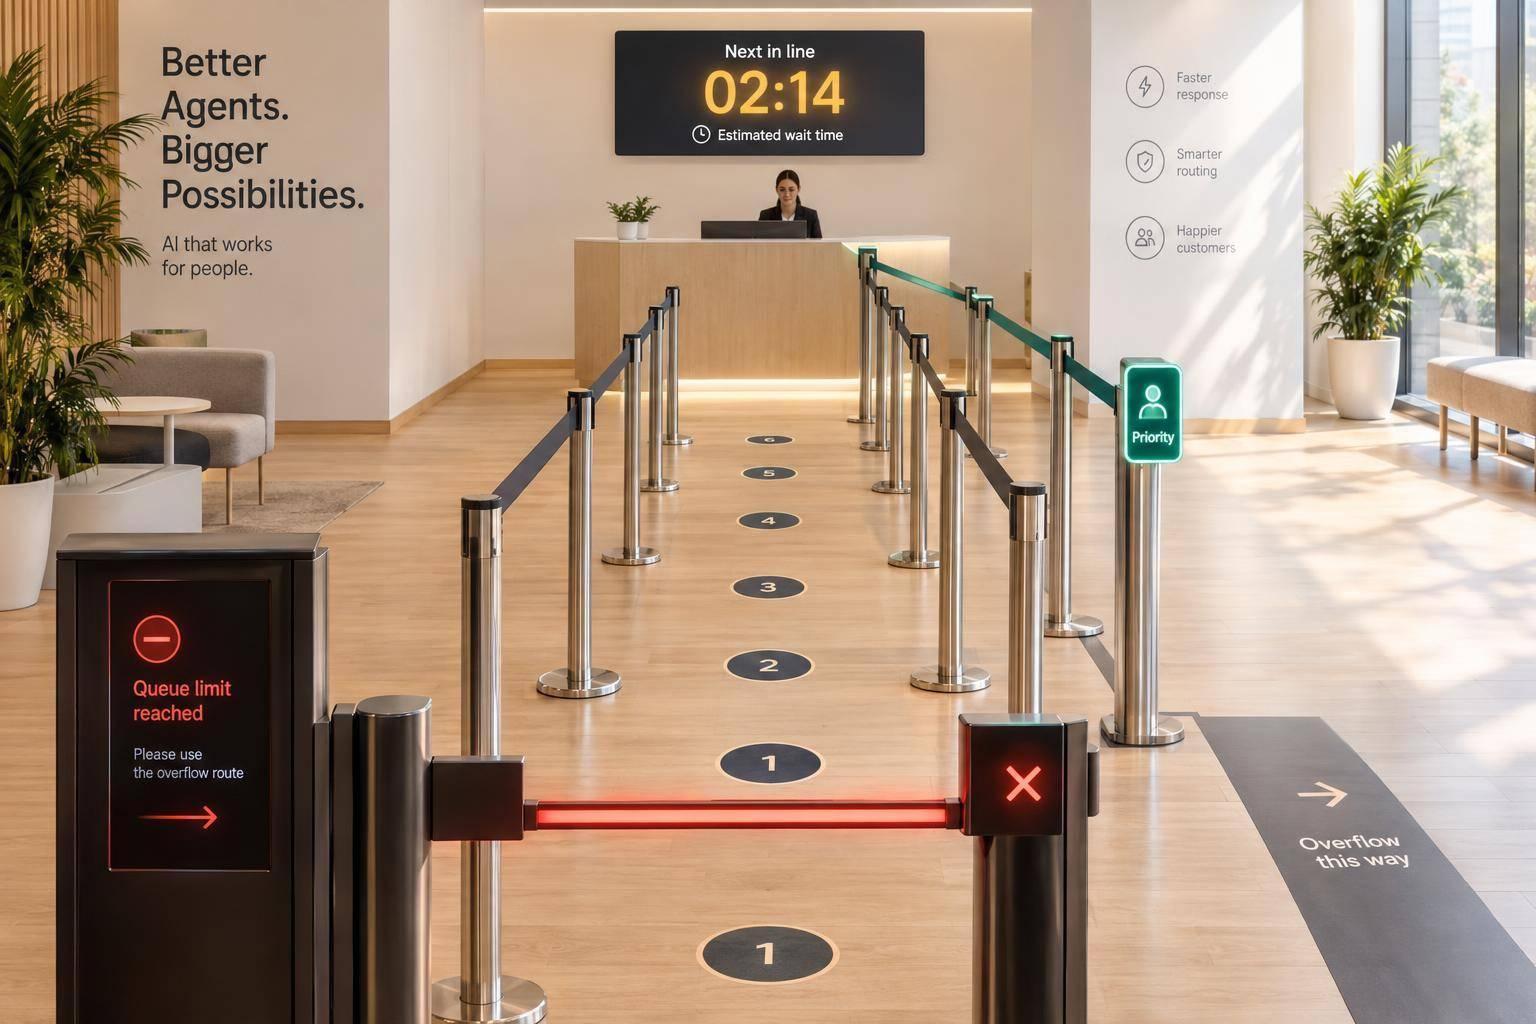
Use bounded queues, single deadlines and priority-based shedding to control AI agent load and protect latency under bursts.
Read more
Run independent tool calls concurrently with permission checks, timeouts and safe retries to cut latency while preserving state.
Read more
Compare extractive trimming and generated summaries in RAG pipelines, balancing token cost, latency and evidence fidelity.
Read more
Compare source snapshots with the published index, validate chunk and embedding hashes, run retrieval tests, and republish fixes to stop RAG drift.
Read more
Measure AI agent cost as total delivery spend / accepted tasks — include retries, tools and human review to reveal true per-task cost.
Read more
Why ConfigMap edits don't restart Pods, how mounts and env vars behave, and when to use restarts, checksums, or reloaders.
Read more
Measure end-to-end flow, model pipelines as DAGs, split runner pools and scale from queue signals to improve CI/CD throughput.
Read more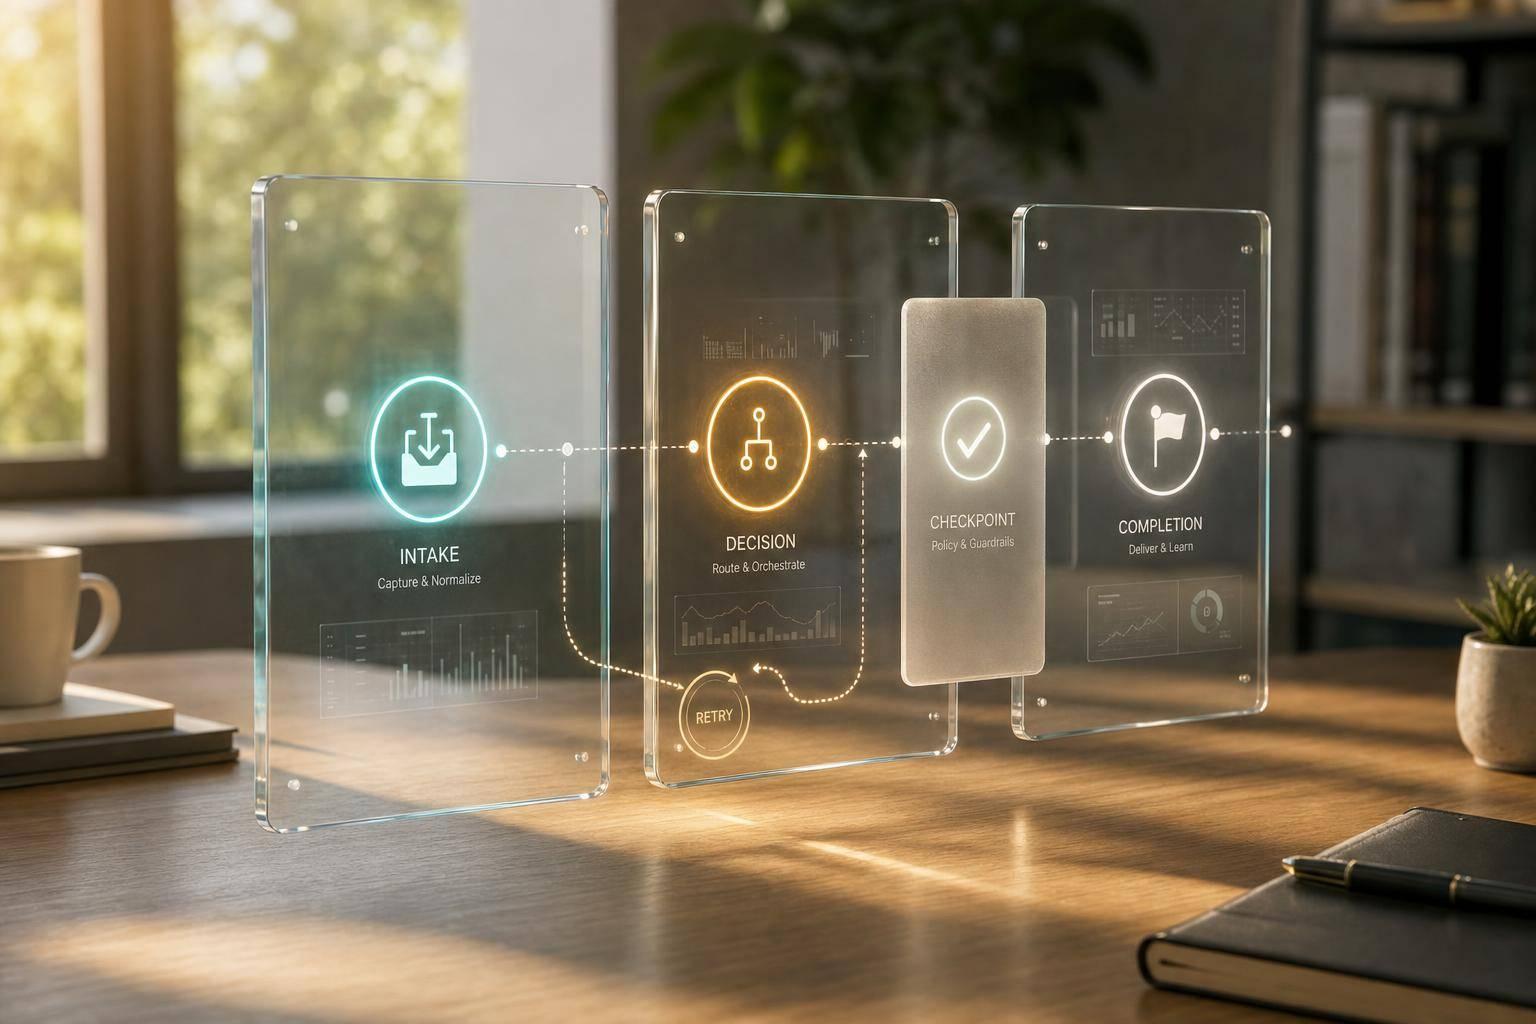
Route AI agent tasks by risk with event-driven orchestration: stateful workflows, approval gates, retries and observability.
Read more
DNS-based global load balancers prevent regional outages, reduce latency and unify multi-region services under one hostname.
Read more