AI Agent Stagnation: How Progress Checks Catch Stalls
Measure verified results, enforce windowed progress checks and block further calls when AI agents show no measurable improvement.
Read moreBlog posts in the Resource Allocation category
Measure verified results, enforce windowed progress checks and block further calls when AI agents show no measurable improvement.
Read more
Track every model call, normalise tokens, convert rates to GBP, attribute costs to tasks and monitor spend.
Read more
Use iteration, token and spend caps plus atomic budget reservation to stop agent loops and control AI costs.
Read more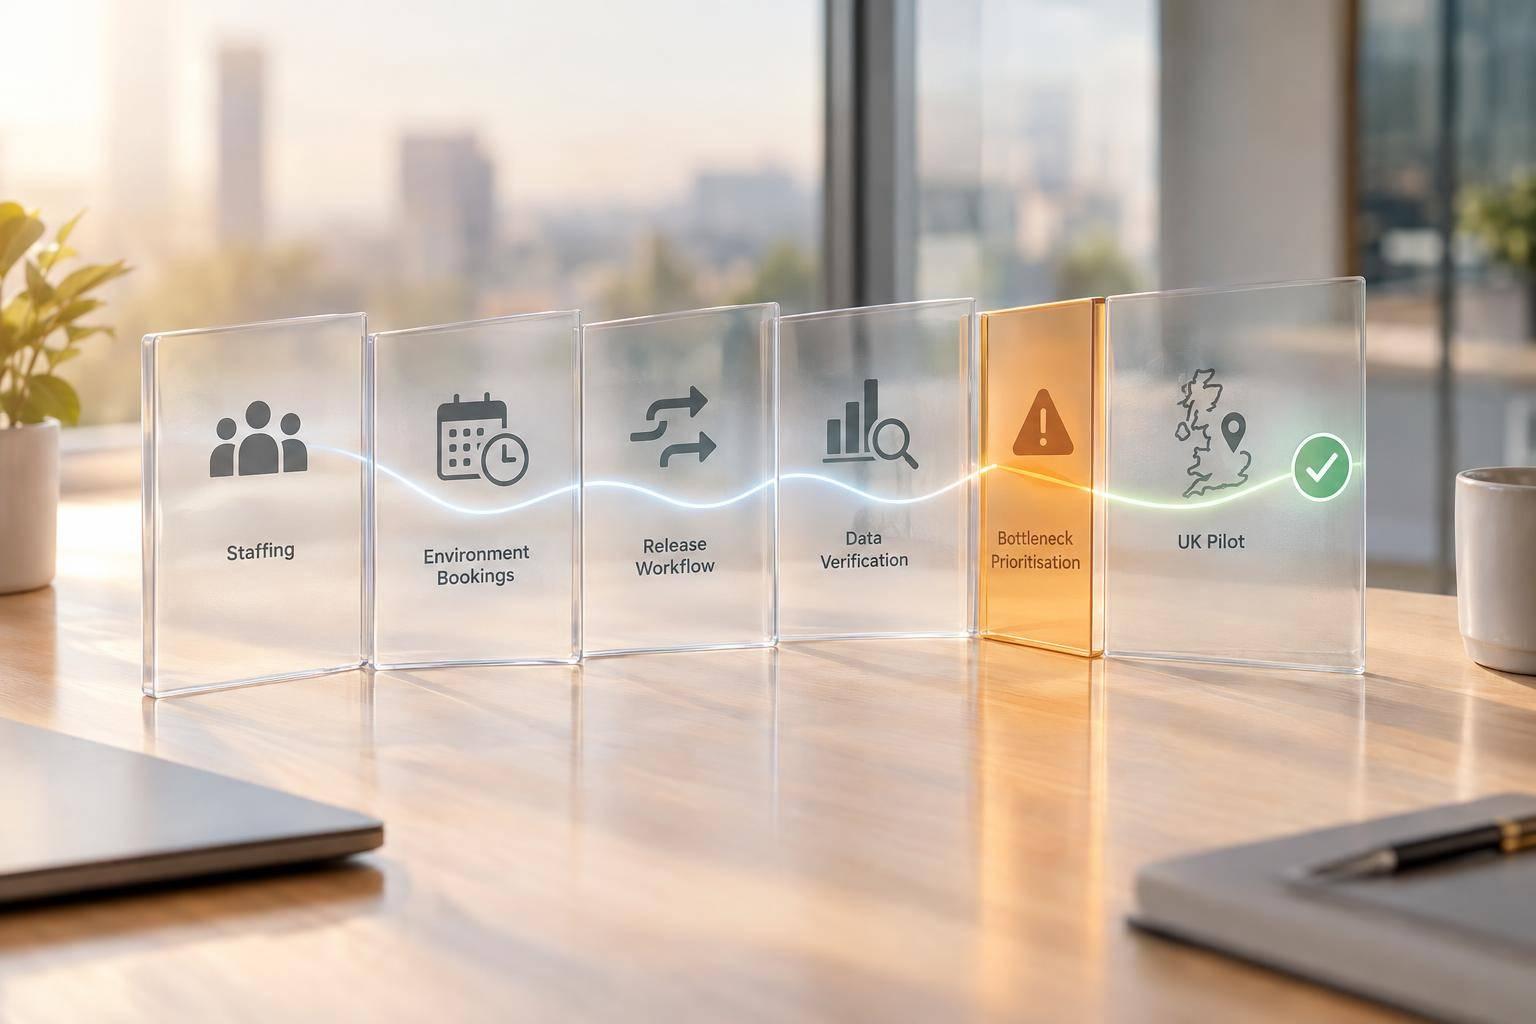
Compare six tools for staffing, environment bookings and release workflows; prioritise bottlenecks, verify data and run a UK pilot.
Read more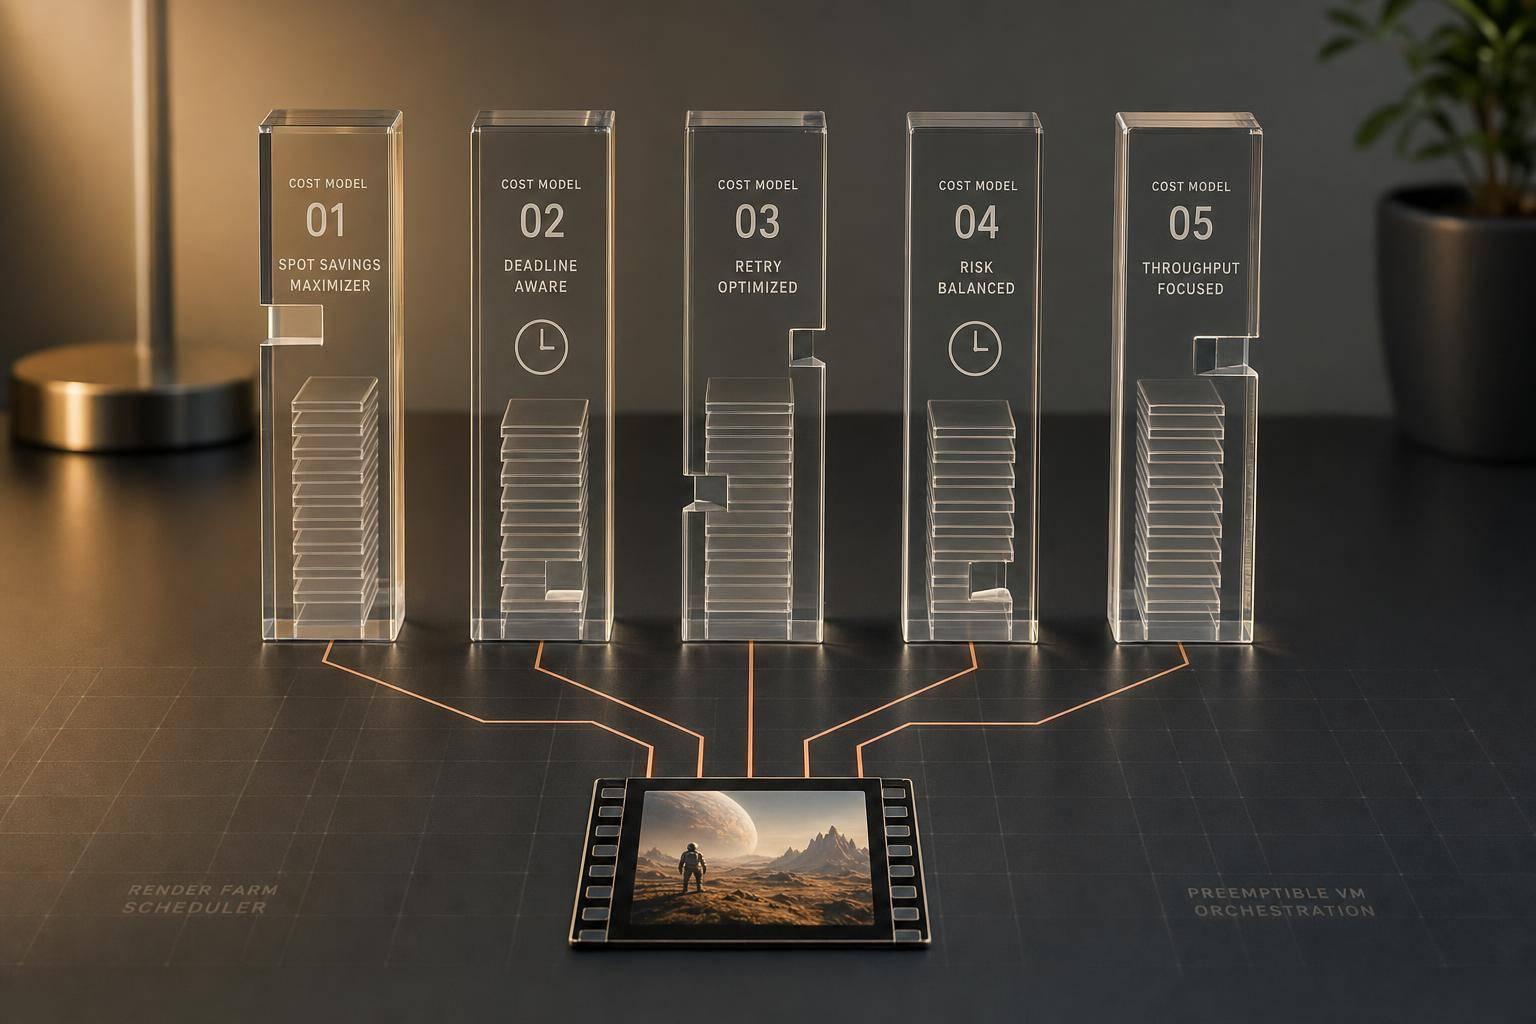
Compare five preemptible VM models for render farms to find true cost per finished frame, accounting for retries and deadline risk.
Read more
Configure rolling updates, probes and cluster headroom so autoscaling can schedule surge Pods and keep Kubernetes rollouts zero‑downtime.
Read more
Compare seven Kubernetes rightsizing tools by control model, automation and cost impact to pick a safe, practical fit for your team.
Read more
Measure end-to-end flow, model pipelines as DAGs, split runner pools and scale from queue signals to improve CI/CD throughput.
Read more
Size cloud commitments to the steady AI usage floor, favour inference, use 60–90 day baselines and stagger renewals.
Read more
Ten practical steps to cut hybrid cloud spend: centralise visibility, rightsize compute, tier storage, curb egress and assign ownership.
Read more
Compare cost‑optimised, performance‑optimised, balanced and static AI allocation strategies to align latency SLOs, utilisation and spend.
Read more
Model cloud spend in GBP using cleaned billing, driver-based forecasts and four reusable scenarios to defend budgets.
Read more