How AI Agents Trace Root Cause in DevOps
AI agents cut DevOps RCA time by linking clean telemetry, traces and change records to surface ranked root-cause hypotheses for human approval.
Read moreBlog posts in the Performance category

AI agents cut DevOps RCA time by linking clean telemetry, traces and change records to surface ranked root-cause hypotheses for human approval.
Read more
Remove avoidable cross-cloud distance, scale on real signals, and unify observability to stop multi-cloud slowdowns.
Read more
Compare 10 cloud SLA monitoring tools by uptime checks, alerting, latency views and pricing to find the right fit for your DevOps team.
Read more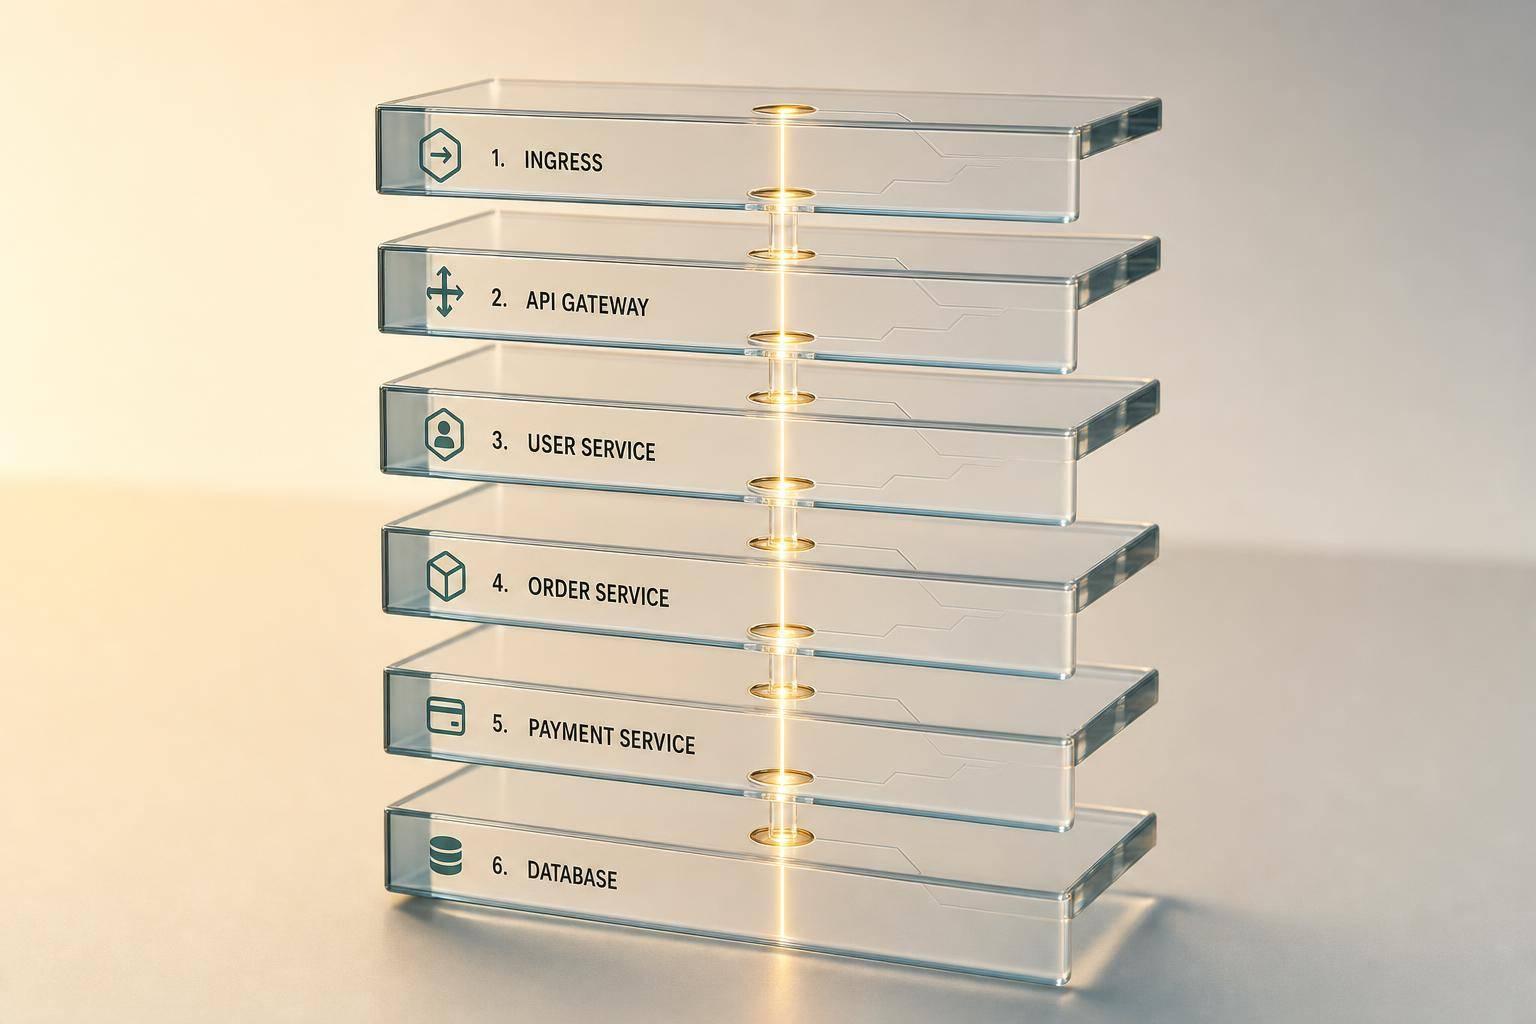
Instrument Kubernetes with OpenTelemetry: six end-to-end tracing patterns, propagation rules, Collector options and common break points.
Read more
Compare cost‑optimised, performance‑optimised, balanced and static AI allocation strategies to align latency SLOs, utilisation and spend.
Read more
Match TTLs to content: long for versioned assets, short micro-caches for bursty APIs to reduce origin egress, compute and DB costs.
Read more
Compare autoscaling strategies—conservative, headroom, spot, bin-packing and multi-pool—to balance cloud cost and p95 latency.
Read more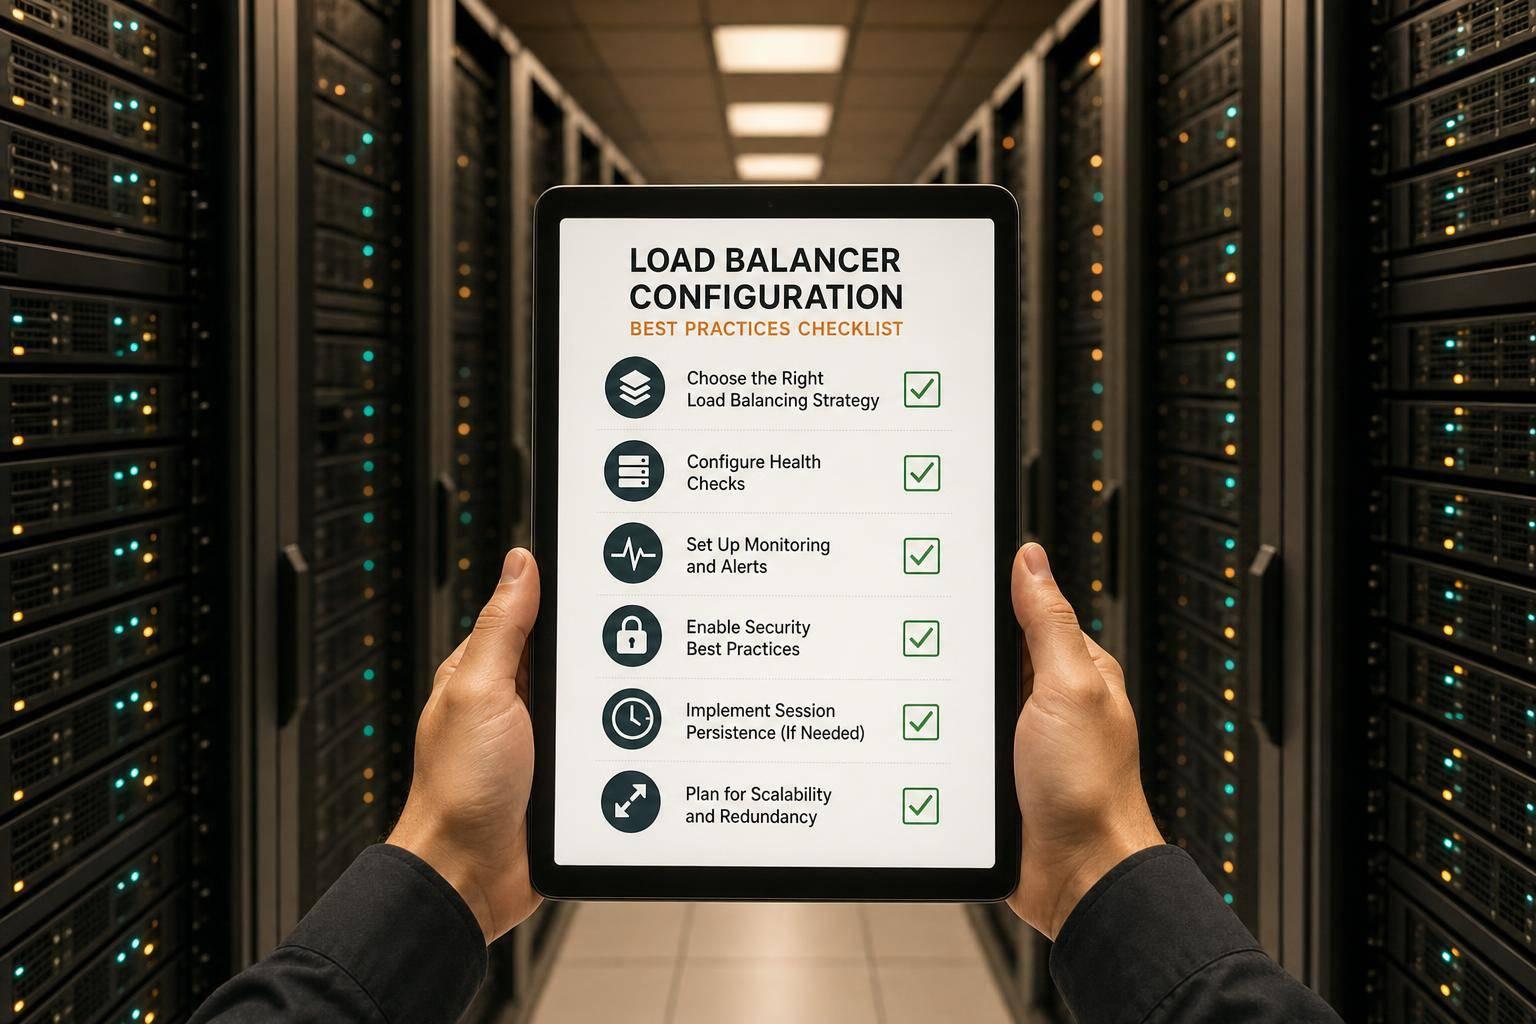
Practical checklist to configure resilient, secure load balancers: layer choice, backends, health checks, TLS, timeouts and failover.
Read more
Set proper min/max capacity, use baked AMIs, choose workload metrics, enable 1‑minute monitoring and tune warmup for steady Auto Scaling.
Read more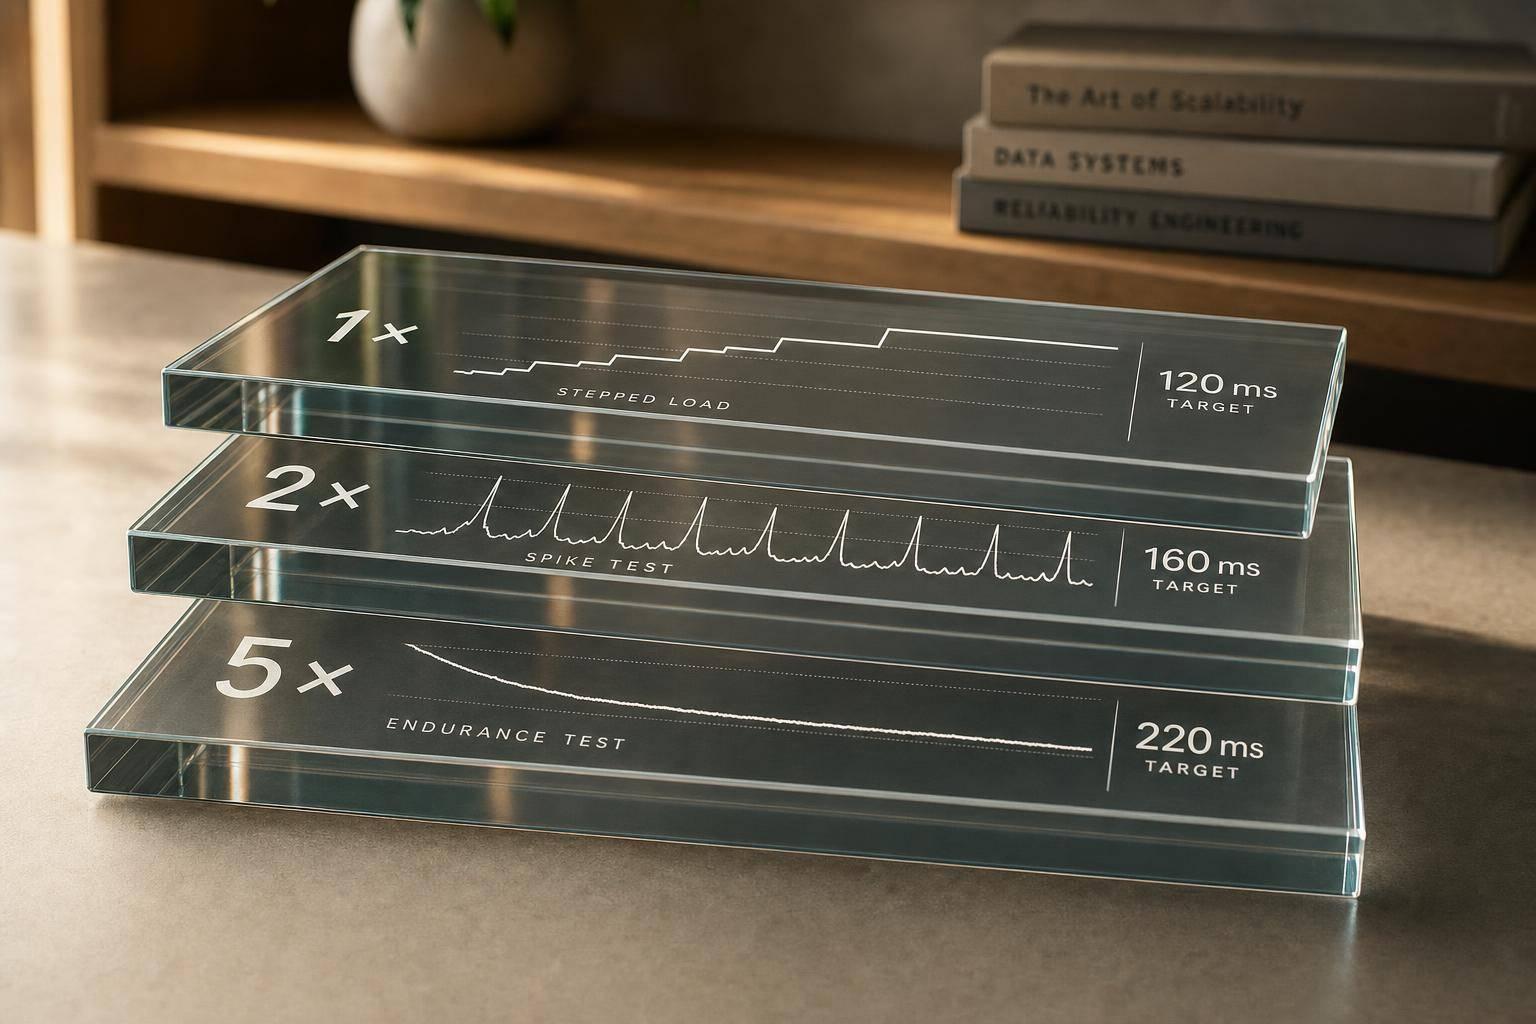
Test databases at 1×, 2× and 5× scale: set numeric SLAs, mirror production, run stepped/burst/endurance tests and fix bottlenecks.
Read more
Small latency gaps hide bigger trade-offs; region choice, storage tier and autoscaling usually decide which cloud is best for UK apps.
Read more
Six core metrics—latency, traffic, UX, uptime, capacity and cost—with thresholds and standard labels for consistent multi‑cloud monitoring.
Read more